Why AI Hallucinates and How We Fix It
Team Ilm Ora · 20 October 2026
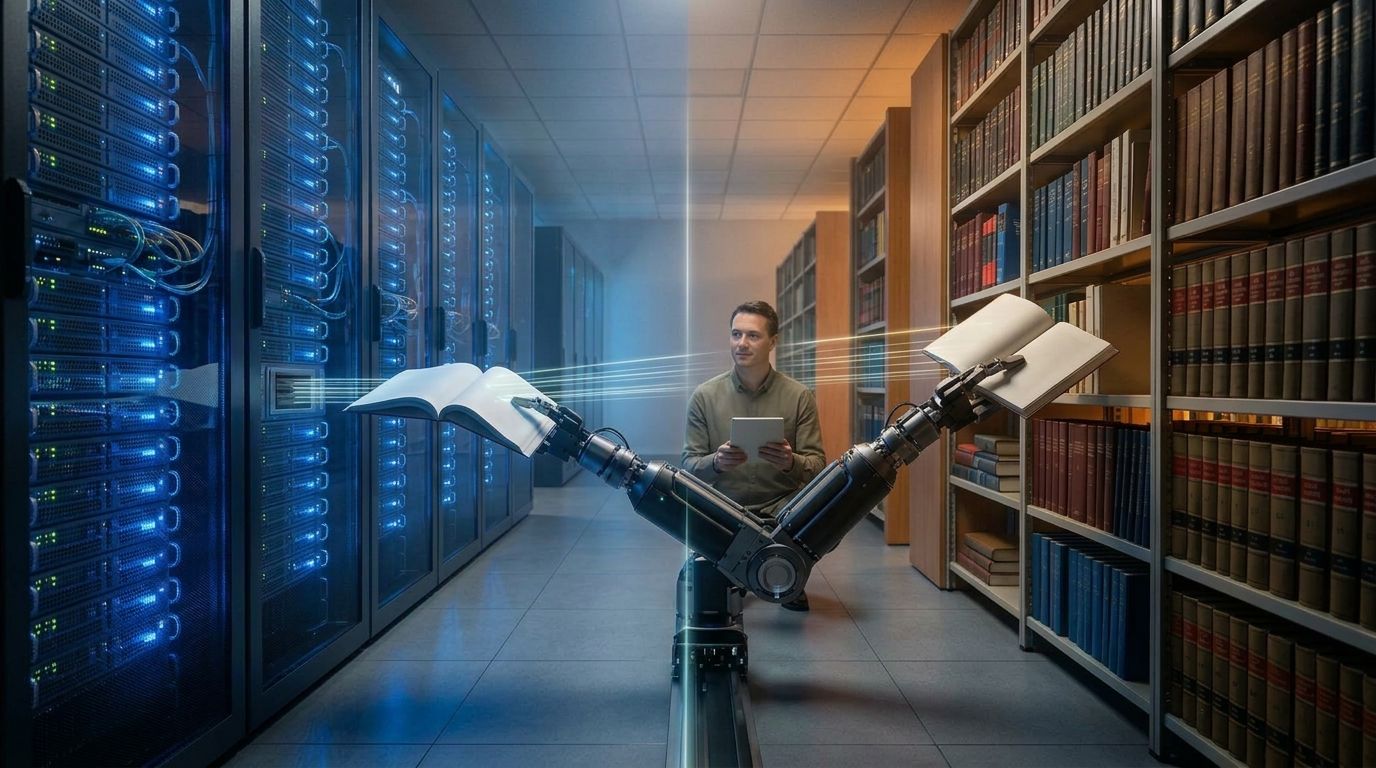
When you ask an advanced artificial intelligence a question, it responds with fluent, confident sentences that sound like an expert historian or scientist. However, unlike traditional databases that retrieve verified factual records, language models generate answers word by word based on statistical probabilities. When probabilities lead the model down an incorrect path, it invents entirely false facts with absolute conviction, an issue known as an AI hallucination. Understanding why probabilistic generation creates these confabulations, alongside how modern engineers use retrieval-augmented generation and multi-agent debate to verify facts, is essential for building trustworthy digital systems.
Predicting the Next Word Through Probability
To understand why language models hallucinate, we must look at how they generate text. A large language model does not understand facts, logic, or truth the way a human does. Instead, it acts as an advanced probability engine trained on vast libraries of text. When you type a prompt, the model calculates which word statistically follows next in the sequence, then calculates the word after that, continuing until the response is complete. Because the model optimizes for linguistic fluency rather than factual truth, a statistically likely sentence can sometimes be entirely factually incorrect.
Grounding Models with Retrieval-Augmented Generation
To fix the problem of fabricated answers, computer scientists developed Retrieval-Augmented Generation, or RAG. Instead of relying purely on the model's internal memory, a RAG system pauses before generating an answer. It searches verified external databases, academic journals, or live web indexes to retrieve relevant factual documents. The system then feeds those verified documents directly into the prompt context, commanding the AI to base its response strictly on the provided evidence, dramatically reducing fabrication rates.
Multi-Agent Debate and Cross-Examination
Another powerful mitigation strategy involves setting up multiple AI agents to cross-examine one another. In this framework, one AI model generates an initial answer, while a secondary critic model reviews the text, checks citations, and challenges logical inconsistencies. If the critic finds weak points, the primary model revises its answer before showing it to the human user. This internal debate mimics human peer review, catching errors before they reach the public.
Building Trustworthy Digital Assistants
Eliminating hallucinations is the primary key to making artificial intelligence reliable for critical fields like medicine, law, and education. By combining statistical language generation with external factual grounding and rigorous multi-agent verification, engineers are transforming conversational models from creative storytellers into dependable, truthful assistants.
Fluency is no substitute for truth, and building trustworthy artificial intelligence requires anchoring probabilistic guesswork in verified factual evidence.